Data entering LLMs and analytical systems is prone to being mixed with personal information such as names, phone numbers, email addresses, bank account numbers, and IP addresses. Even if you instruct the model “do not output personal information,” it’s too late if the original text has already been sent to an external model or log.
Microsoft Presidio is an open-source toolkit that finds and de-identifies Personally Identifiable Information (PII) in text, images, and structured data. The core is a separation of responsibilities: the Analyzer finds PII candidates and their locations, and the Anonymizer masks, deletes, replaces, or encrypts those locations.
This article will focus on what Presidio is, how it differs from regular expression filters, how the Analyzer and Anonymizer collaborate, where it should be placed in LLM and RAG pipelines, and its limitations.
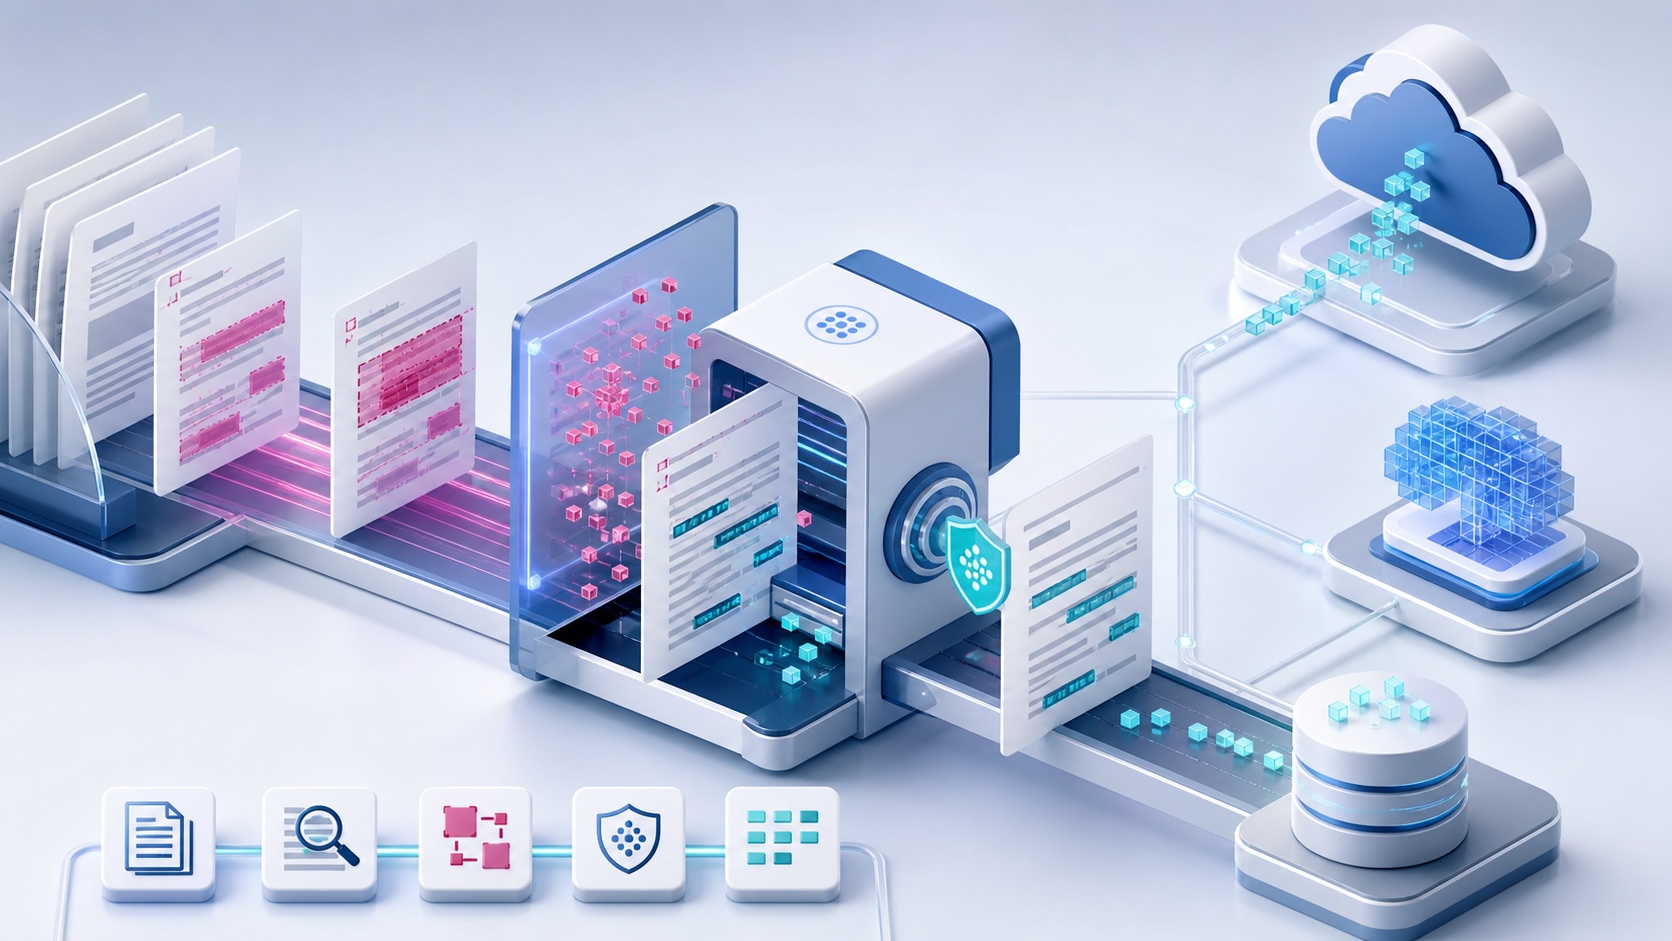
Presidio in a single sentence
Presidio is not a platform that orchestrates entire data, but a PII detection and de-identification engine that applications can call.
원문
  → Presidio Analyzer: 엔터티 종류·위치·점수 탐지
  → 정책 결정: 무엇을 어떻게 처리할지 선택
  → Presidio Anonymizer: 마스킹·삭제·치환·해시·암호화
  → 비식별화된 데이터
It can be embedded within an application as a Python library, or the Analyzer and Anonymizer can be run as HTTP services or containers. Although it started as a Microsoft project, official documentation and container deployment paths are now moving to Data Privacy Stack, so it’s best not to use old MCR images or outdated document links.
Why a few regular expressions aren’t enough
Values with clear formats, like email addresses or credit card numbers, can be found with regular expressions. However, values whose meaning changes with context, such as people’s names, locations, or organization names, are difficult to judge by patterns alone. A string of numbers could also be a phone number, order number, date, or simple quantity.
Presidio Analyzer runs multiple EntityRecognizers simultaneously. The official documentation explains that it can combine regular expressions, Named Entity Recognition (NER), checksums, contextual words, and user-defined logic. Each result is typically expressed as an entity type, start/end position, and confidence score.
from presidio_analyzer import AnalyzerEngine

analyzer = AnalyzerEngine()
results = analyzer.analyze(
    text="연락처는 010-1234-5678입니다.",
    language="ko"
)
Do not assume that this example will immediately yield desired results in Korean. You should check the NLP model and Recognizer support status for each language, and augment organization-specific entities like domestic phone numbers, resident registration numbers, and business registration numbers with custom Recognizers and test data.
Key Components
| Component | Role | What to decide in practice |
| — | — | — |
| AnalyzerEngine | Coordinates Recognizers and NLP engines to detect PII candidates | Language, target entities, score threshold |
| EntityRecognizer | Detector that finds specific PII types | Regular expressions, NER, external models, user-defined logic |
| RecognizerRegistry | Manages the list of Recognizers to use | Activation scope by country/business |
| NlpEngine | Language processing such as tokenization, NER | spaCy, Transformers, Stanza and models |
| Context Aware Enhancer | Enhances detection scores with surrounding words | Contextual words and false positive adjustment |
| AnonymizerEngine | Applies transformation operations to detected locations | De-identification policy per entity |
| Operator | Executes replace, redact, mask, hash, encrypt, etc. | Reversibility, re-identification risk, key/Salt management |
Presidio does not decide “what information is personal information” on behalf of an organization. Detectable entities and actual regulatory/contractual protected data may differ, so a separate mapping should be done at the policy layer.
What does the Analyzer return?
The Analyzer returns candidate segments without changing the original text. For example, it might indicate that characters 10 through 23 of a string are a PHONE_NUMBER with a confidence score of 0.85. This separation allows applications to apply different policies based on the same detection results.
- Completely delete from logs.
- Leave only the last four digits on the consultation screen.
- Replace with a pseudonymized value that can link the same individual for statistical analysis.
- Encrypt for authorized business processing and restore with a separate key.
The score is not a probability guaranteeing factual accuracy. Increasing the threshold reduces false positives but may increase false negatives, while lowering it captures more but might obscure legitimate data.
How does the Anonymizer change data?
Presidio Anonymizer receives segment information from the Analyzer and applies Operators. The official documentation describes operations such as replace, redact, mask, hash, encrypt, custom, and keep.
| Operator | Result | Suitable for | Caveats |
| — | — | — | — |
| replace | Replaces with a value like |
LLM prompts, logs | Original value cannot be restored |
| redact | Deletes the corresponding string | External sharing, minimal collection | Context may be broken |
| mask | Changes some characters to * etc. | Consultation screen, confirmation UI | Re-identification possible with remaining characters |
| hash | Hashes using Salt | Statistical linking, duplicate analysis | Consider Salt management and brute-force attacks |
| encrypt | Encrypts with a key | Tasks requiring authorized re-identification | Key must be separated from body/prompt |
| custom | Replaces with a user-defined function | Pseudonym generation, business rules | Need to verify function security and determinism |
The latest documentation explains that hash operations by default use a random Salt per entity. To link the same personal information across multiple records with the same hash, a consistent Salt must be provided directly, but if that Salt is leaked, the risk of re-identification increases. Salt and encryption keys should be managed in trusted storage like KMS, Key Vault, or Secrets Manager, not in prompts or general configuration files.
Why place Presidio before LLMs?
Simply checking that an LLM does not output personal information is not enough to prevent input exposure. The most basic deployment is to pass the original text through the Analyzer and Anonymizer before calling the model.
사용자 입력·업로드 문서
  → Presidio 탐지
  → 업무 정책에 따른 비식별화
  → LLM 호출
  → LLM 출력 재검사
  → 사용자
There’s a reason why both input and output need checking. Inputs contain personal information provided by the user, and outputs may contain personal information retrieved by the model from conversation history, search documents, or tool results. However, indiscriminately masking the same sentence at multiple stages can damage context and quality, so the purpose of each boundary must be clear.
Where should it be placed in RAG?
RAG involves finding documents related to a query in a Vector DB and inserting original text chunks into the LLM prompt. Presidio is not a tool that meaningfully inspects embedding vectors themselves. It should inspect the original text chunks returned after retrieval.
The recommended flow is as follows:
Application: 인증·Tenant 확정
  → Retrieval API: Tenant Filter와 문서 권한 적용
  → Vector DB 검색
  → 반환된 원문 청크
  → Presidio: PII 탐지·비식별화
  → LLM 프롬프트 조립
Presidio does not determine tenant permissions. Searching for documents that should not be accessed and then only masking personal information is not proper authorization. Document access control and Security Trimming should be applied first, and then personal information in the allowed original text should be further inspected.
If used with NeMo Guardrails, Presidio can be called from a Custom Action in the Retrieval Rail or within an application-owned search API. NeMo orchestrates the overall LLM flow, and Presidio handles PII in the requested text.
Library vs. HTTP Service: Which to choose?
For Python applications, installing presidio-analyzer and presidio-anonymizer in the same process is the simplest approach. There’s no network transmission, and fine-grained customization is easy, but NLP models consume application memory and startup time.
If applications in multiple languages or multiple teams use common policies, the Analyzer and Anonymizer can be separated into HTTP services. The official installation documentation currently points to data-privacy-stack images on GHCR, and for production environments, it recommends pinning to explicit release tags instead of `latest`.
podman run -d --name presidio-analyzer
  -p 5002:3000
  ghcr.io/data-privacy-stack/presidio-analyzer:latest

podman run -d --name presidio-anonymizer
  -p 5001:3000
  ghcr.io/data-privacy-stack/presidio-anonymizer:latest
While `latest` is convenient for tutorials, production deployments should pin to a verified version tag and image Digest. Service separation is advantageous for centralizing policies, but since original personal information travels over the network once more, TLS, service authentication, request log masking, and timeouts are necessary.
When to use Presidio
- Consistently detect and mask PII in LLM prompts or responses.
- Reuse the same de-identification policy for logs, data analysis, and external sharing.
- Need NER, context, checksums, and custom Recognizers in addition to regular expressions.
- Need to choose between Python library and HTTP service deployment.
- Need to apply different policies (deletion, partial masking, hashing, encryption) per entity.
Conversely, if input fields are strictly structured and a small service only needs to remove one email field, simple validation code might be more appropriate. Presidio’s value increases when repeatedly processing diverse unstructured text and multiple policies.
Limitations you must know
Presidio is not a complete DLP product that automatically finds all personal information. There are false positives and false negatives depending on the language and domain, and new identifiers and combined identifiers may not be known by default Recognizers. Even if a name is removed, combining workplace, rare diseases, dates, and locations can still re-identify an individual.
Furthermore, if detection results are left as-is in logs, the original text intended for protection can be duplicated in observation systems. Debugging decision traces, API requests/responses, error messages, and sample data should all be treated as personal information processing targets.
Performance also needs consideration. Running NLP models alongside regular expressions can improve accuracy but increases CPU/GPU usage, memory, and latency. Thresholds and Recognizers should be adjusted with test sets that reflect the language, length, and entity distribution of actual data.
Conclusion
Microsoft Presidio is not a guardrail platform responsible for overall LLM security. It is a specialized engine that provides an Analyzer to find PII candidates in original text and an Anonymizer to change values according to policy.
The reason to use Presidio is to make personal information protection a data processing step executed before and after model calls, rather than “a sentence asking the model.” However, tenant permissions, legal processing basis, encryption keys, and final access approval must be handled by the application and trusted security layers.
The correct deployment is simple: first enforce authentication and document permissions, then detect and de-identify allowed original text with Presidio, and finally deliver it to LLMs or analysis systems. By adhering to this separation of responsibilities, Presidio becomes a powerful component that substantially reduces the scope of personal information exposure in LLM, RAG, and log pipelines.
Leave a Reply