When using generative AI and large language models, one question arises:
Can LLMs be perfectly controlled if sufficient safeguards are applied?
To get straight to the point, while it is possible to significantly reduce the risks of LLMs, it is realistically very difficult to perfectly control them to behave exactly as desired in all inputs and situations.
The reason is that LLMs are not systems that merely execute human-written rules like conventional software; they are neural network models that learn statistical patterns from vast amounts of data.
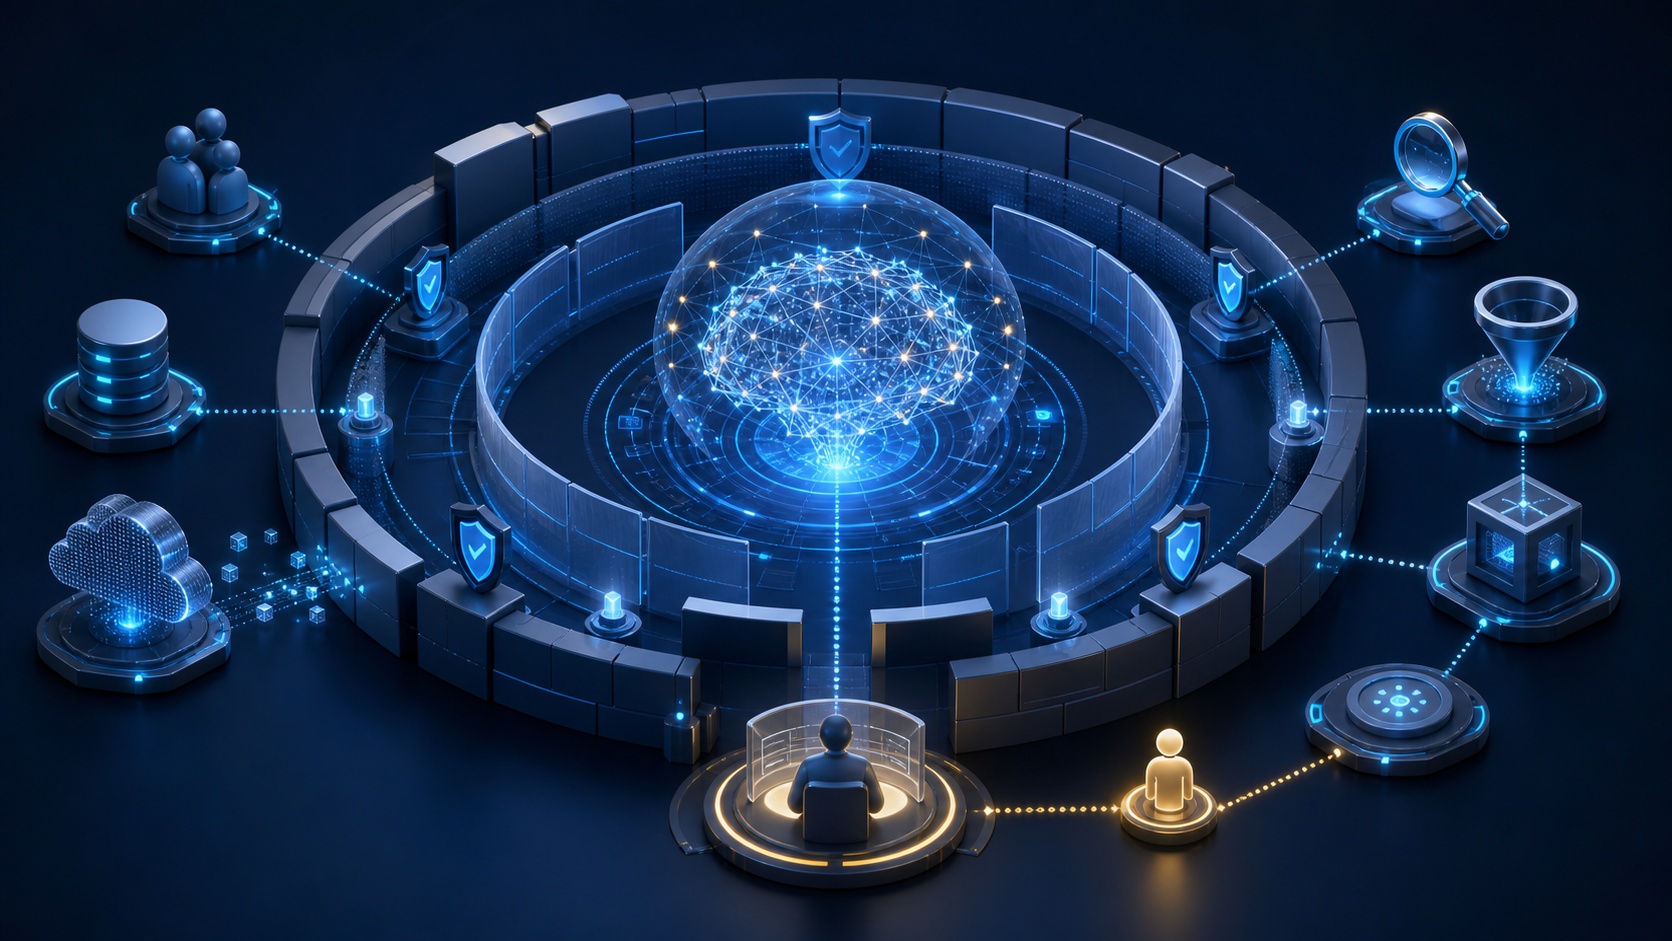
In this article, we will organize generative AI security not as “a technology to perfectly constrain the model,” but from the perspective of “a structure that prevents damage from spreading to actual systems even if the model fails or is bypassed.”
Artificial Neural Networks Started from Biological Neurons
Artificial neural networks were inspired by how the human brain and nerve cells transmit information.
It is a mathematical simplification of the concept of receiving multiple inputs, calculating their importance, and transmitting a signal to the next neuron if certain conditions are met.
입력값
→ 가중치 적용
→ 여러 입력값 결합
→ 활성화 함수
→ 출력값 전달
This structure evolved from early artificial neural networks through CNN, RNN, and LSTM to Transformer and modern LLMs.
인공신경망
→ CNN·RNN
→ LSTM·Attention
→ Transformer
→ GPT·Llama 등 LLM
However, artificial neural networks are not exact replicas of the human brain. While they draw basic ideas from biological neurons, modern LLMs are closer to large-scale mathematical models where countless parameters learn patterns from data.
Therefore, it is more accurate to explain that it is not uncontrollable because it mimics biological structures, but rather because the model is an excessively large and complex probabilistic system, making all its behaviors difficult to predict.
LLMs Are Different from Rule-Executing Programs
Traditional programs execute conditions and commands written by developers.
if user_role == "admin":
    allow_access()
else:
    deny_access()
If the input values and program state are the same, the results can be predicted relatively clearly.
In contrast, LLMs calculate the most probable next token based on the input context.
사용자 입력
→ 문맥과 토큰 관계 분석
→ 다음 토큰의 확률 계산
→ 토큰 선택
→ 같은 과정을 반복
For example, a model can calculate probability distributions like this:
"보안" 다음에 올 토큰

정책: 35%
점검: 25%
취약점: 20%
시스템: 10%
기타: 10%
The output of an LLM is generated by repeating these probability calculations. The results can vary depending on generation settings like Temperature, previous conversation content, system prompts, or external documents.
In other words, an LLM is not a database that looks up predefined answers, but a probabilistic model that generates results based on context.
Reasons Why Perfect Control Is Difficult
The difficulty in fully predicting LLM behavior is not merely due to randomness in the output.
Models generate results through complex interactions between billions to trillions of parameters. It is difficult for humans to clearly explain at every step how a specific input leads to a final answer through internal calculations.
Furthermore, actual LLM services do not consist of only the model.
사용자 입력
→ 시스템 프롬프트
→ LLM
→ RAG 검색
→ 외부 도구 호출
→ 데이터베이스·API
→ 최종 응답
The following uncertainties also exist:
- Errors and biases contained in training data
- Failure to generalize to novel inputs
- Changes in results due to prompt phrasing
- Direct/indirect prompt injection
- Malicious instructions included in RAG documents
- Misuse of permissions during tool calls
- Changes in behavior due to model updates
- Vulnerabilities arising from combining multiple components
Therefore, simply increasing the safety of the model does not automatically ensure the security of the entire system.
The OWASP GenAI Security Project’s LLM Top 10 also illustrates this perspective well. The 2025 list includes items such as Prompt Injection, Sensitive Information Disclosure, Improper Output Handling, Excessive Agency, System Prompt Leakage, and Vector and Embedding Weaknesses. Most of these are not problems that end with “the model gave a bad answer,” but rather system security issues that arise when the model is connected to applications, tools, and data.
Distinguishing Between Unpredictability and Security Vulnerabilities
Not every instance where an LLM generates an unexpected answer is a security vulnerability.
For example, a model hallucinating and providing factually incorrect information is a reliability issue. However, if the model’s incorrect answer is executed as a system command or used in critical decision-making, it can lead to an actual security incident.
모델의 잘못된 출력
→ 사용자에게 참고 정보로만 제공
= 품질·신뢰성 문제

모델의 잘못된 출력
→ 서버 명령이나 금융 거래로 자동 실행
= 보안 사고 가능성
The unpredictability of an LLM itself is not necessarily a vulnerability.
However, if an unpredictable model is granted excessive privileges and connected to external systems without verification, that uncertainty can turn into a vulnerability.
Generative AI Security Starts with Distrust
The most important principle in LLM security is not to treat the model as a trustworthy security principal.
Just because the model is instructed “do not disclose important information” does not mean that all secret information to which it has actual access can be passed to it. A system prompt is also just an instruction to the model, not a security boundary.
Therefore, security controls must be enforced externally to the model.
LLM을 완전히 신뢰하지 않음
→ 입력 검증
→ 출력 검증
→ 최소 권한 적용
→ 도구 호출 통제
→ 중요 작업 승인
→ 감사 로그와 모니터링
→ 지속적인 공격 테스트
Do not trust inputs and external documents
Malicious instructions can be included not only in user inputs but also in webpages, emails, PDFs, and RAG documents.
All data read by the LLM should be treated as potentially attacker-controlled input.
Verify outputs before execution
SQL, code, commands, or API arguments generated by an LLM should not be executed directly.
Procedures such as schema validation, allow-listing, policy checks, and execution environment isolation are necessary.
Provide only the minimum necessary privileges
Tools connected to an LLM should be granted only the minimum privileges required to perform their tasks.
For example, if an agent that only needs to search emails is also granted permission to send or delete emails, a model’s mistake could escalate into a real incident.
Critical operations require human approval
High-risk operations such as payments, account deletion, permission changes, and external transfers should implement Human-in-the-Loop approval.
LLM의 작업 제안
→ 정책 검사
→ 사용자 또는 관리자 승인
→ 실제 실행
Test with the assumption of failure and bypass
Passing a single prompt test does not mean the model is secure.
Continuous verification is necessary using various variations such as phrasing changes, multilingual inputs, encoding, role-playing, and indirect prompt injection.
Damage Limitation Structure Is More Important Than Perfect Defense
Setting the goal of generative AI security as “making the model never do anything wrong” makes realistic security design difficult.
A more realistic goal is:
To ensure that even if the model makes a wrong judgment or is bypassed by an attack, important data and systems are not harmed.
This connects to the existing Zero Trust principle of security.
Just as users are not implicitly trusted, LLMs should not be implicitly trusted. The model’s output should be treated as a request or suggestion, and the actual authorization decision and execution should be determined by a separate security layer.
사용자
→ LLM
→ 보안 Wrapper
   ├── 인증 확인
   ├── 권한 검사
   ├── 입력값 검증
   ├── 정책 적용
   └── 승인 여부 확인
→ 외부 도구 실행
In this structure, even if the LLM follows an attacker’s instructions, the security Wrapper can block unauthorized actions.
The direction emphasized by the NIST AI Risk Management Framework is similar. AI risk management is not a one-time checklist but rather a management system that must be repeatedly performed throughout the entire development, deployment, and operation process through Govern, Map, Measure, and Manage activities. Generative AI security should also be designed with operational policies, permissions, verification, and monitoring, rather than relying solely on the performance or safety filters of a single model.
Starting Point of Generative AI Security
LLMs offer excellent performance, but they are not systems whose behavior can be perfectly predicted or controlled in all situations.
This does not mean that LLMs cannot be used. It’s like not avoiding cars because of the possibility of accidents, but rather using seatbelts, brakes, and traffic rules together.
Generative AI also needs to acknowledge the model’s limitations and apply multiple security layers together.
Generative AI security begins not with the belief that the model can be perfectly controlled, but with the recognition that the model can fail or be bypassed at any time.
The core of generative AI security is to design systems not to eliminate the model’s unpredictability, but to ensure that this uncertainty does not lead to actual data breaches, privilege misuse, or system compromise.
Leave a Reply