Hello! Welcome to the world of Observability, which makes your systems more transparent. 🚀 Collecting data like metrics, logs, and traces using OpenTelemetry is the first step to understanding your system’s health. But is simply collecting data enough?
If the collected data is inconsistent and its meaning is unclear, it may not be helpful at all when a problem actually occurs. Today, we will delve into how to name attributes for metrics and why it is important.
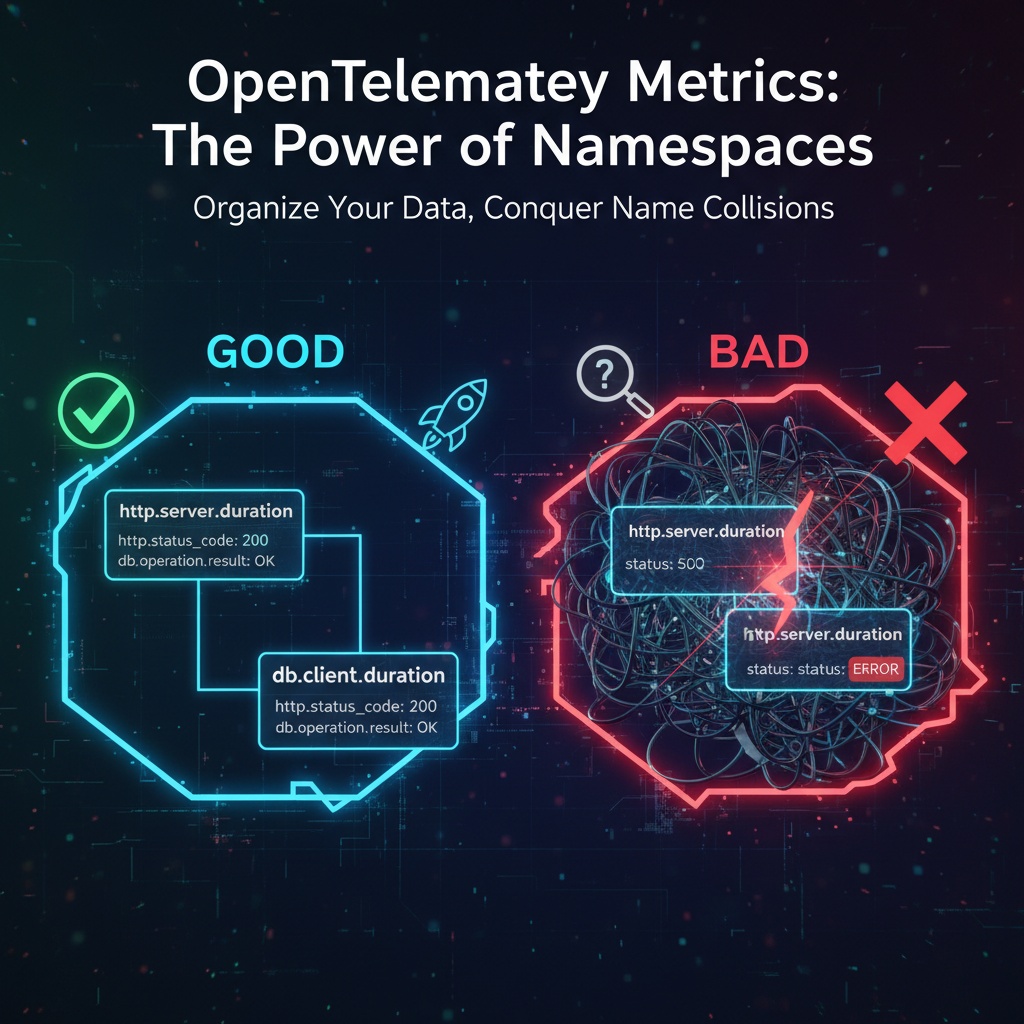
🤔 The Start of the Problem: “The names are the same, it’s confusing!”
Let’s look at the overall context. Imagine we are collecting metrics from various components. For example, we have the following two metrics:
- http.server.duration: HTTP server request processing time
- db.client.duration: DB client query execution time
Both metrics can have an attribute called ‘status’ to indicate the processing result, right?
- HTTP server status: 200, 404, 500, etc. (HTTP status codes)
- DB client status: OK, TIMEOUT, ERROR, etc. (DB processing results)
What if we filter on a dashboard, “Find all requests where status is ERROR”? 🤯 HTTP server 500 errors and DB client ERROR statuses would likely be mixed, making it harder to identify the root cause.
This kind of conflict that arises when attributes with different meanings use the same name is called ‘Name Collision’. To prevent such problems and clarify the meaning of data, OpenTelemetry provides guidelines.
✨ The Solution is in ‘Namespaces’!
The core of the OpenTelemetry guidelines is simple:
If an attribute is uniquely used for a specific metric, name it using that metric’s namespace.
In other words, add a prefix to the attribute name that clearly indicates what kind of attribute it is. The format is usually domain.name.attribute_name.
Let’s change the example above to the correct namespace approach:
- For http.server.duration metric:
- (Bad example 👎) status: 200
- (Good example 👍) http.status_code: 200
- For db.client.duration metric:
- (Bad example 👎) status: “OK”
- (Good example 👍) db.operation.result: “OK” (Example according to Semantic Convention)
By using namespaces this way, http.status_code and db.operation.result are treated as completely different attributes. Now we can perform much clearer and more accurate analysis, such as “HTTP requests with status codes in the 500s” or “DB operation results that are TIMEOUT”.
See it in action with code
To help you understand, let’s look at a simple example code using the Python OpenTelemetry SDK.
# Import necessary libraries
from opentelemetry import metrics
from opentelemetry.sdk.metrics import MeterProvider
from opentelemetry.sdk.metrics.export import ConsoleMetricExporter, PeriodicExportingMetricReader

# Prepare to collect and export metrics
reader = PeriodicExportingMetricReader(ConsoleMetricExporter())
provider = MeterProvider(metric_readers=[reader])
metrics.set_meter_provider(provider)
meter = metrics.get_meter("my-web-server")

# Create http.server.duration metric
http_duration_histogram = meter.create_histogram(
    name="http.server.duration",
    unit="ms",
    description="Measures the duration of inbound HTTP requests."
)

# ✅ Correct way: Define attributes using namespaces
good_attributes = {
    "http.method": "GET",
    "http.status_code": 200,
    "net.peer.ip": "192.168.1.1" # net.* are general network attributes, so use them as is
}
http_duration_histogram.record(150, attributes=good_attributes)
print("✅ [GOOD] Metric with namespaced attributes recorded.")

# ❌ Incorrect way: Define attributes with generic names
bad_attributes = {
    "method": "POST", # 'method' can be used elsewhere, leading to ambiguity
    "status": 500,    # Cannot even tell if 'status' is a number or string, or an HTTP status
    "net.peer.ip": "192.168.1.10"
}
http_duration_histogram.record(520, attributes=bad_attributes)
print("❌ [BAD] Metric with generic attributes recorded.")
Running the above code may output raw data like the following to the console. (Output format varies depending on the Exporter)
// ✅ Raw Metric Data for a good example
{
  "name": "http.server.duration",
  "data": {
    "sum": 150,
    "count": 1,
    // ...
  },
  "attributes": {
    "http.method": "GET",
    "http.status_code": 200,
    "net.peer.ip": "192.168.1.1"
  }
}

// ❌ Raw Metric Data for a bad example
{
  "name": "http.server.duration",
  "data": {
    "sum": 520,
    "count": 1,
    // ...
  },
  "attributes": {
    "method": "POST",
    "status": 500,
    "net.peer.ip": "192.168.1.10"
  }
}
The difference is clear in the raw data, isn’t it? On the good_attributes side, anyone can tell that http.method is an HTTP request method and http.status_code is an HTTP status code. This is how we increase data Interoperability and Consistency.
🧐 Why aren’t other methods correct?
1. Just use generic names (e.g., status, name, type)
- Why not? 😵 As explained above, this is the main culprit of ‘name collision’. An attribute called ‘type’ can be used with dozens of meanings: message type in a message queue, query type in a DB, CPU type in a system, etc. This makes comprehensive data analysis almost impossible.
2. Add a unique prefix to all attributes (e.g., my_http_status, my_db_status)
- Why not? 🗣️ While this avoids name collision, it violates one of OpenTelemetry’s biggest advantages: ‘Semantic Conventions’. OpenTelemetry defines standard names for widely used attributes like http.method and db.statement. Following these standards allows various analysis tools like Grafana and Datadog to automatically recognize data and create great dashboards without additional configuration. Creating our own ‘dialect’ is equivalent to giving up this convenience.
Conclusion: Be clear by following standards! ✨
Observability is not just about collecting data; it’s about understanding the system through that data. Applying namespaces to OpenTelemetry metric attributes is a small but powerful rule that makes this process much smoother and more accurate.
- Key Summary: If an attribute is related only to a specific metric, always use a namespace like http.status_code!
Well-structured data like this will be the best gift to your future self and colleagues, shortening debugging time. 🎁
Leave a Reply