At 2:18 AM, an alert sounded, indicating repeated policy blocks in the LLM service. The application responded that it had blocked the requests, but incident responders need to know more. They must connect who accessed with what permissions, which defense lines were tested, and how far the attack progressed through search, model, and tool execution.
LLM security monitoring is not about finding a single dangerous sentence. It’s about reconstructing the attacker’s behavior by linking the authentication principal, policy decisions, execution paths, actual side effects, and recurring patterns. A request_id is the receipt number for a single request, and a trace_id is the thread that ties together processing steps scattered across multiple services.
The times, identifiers, logs, and metrics in this article are all virtual scenario examples and not actual measurements.
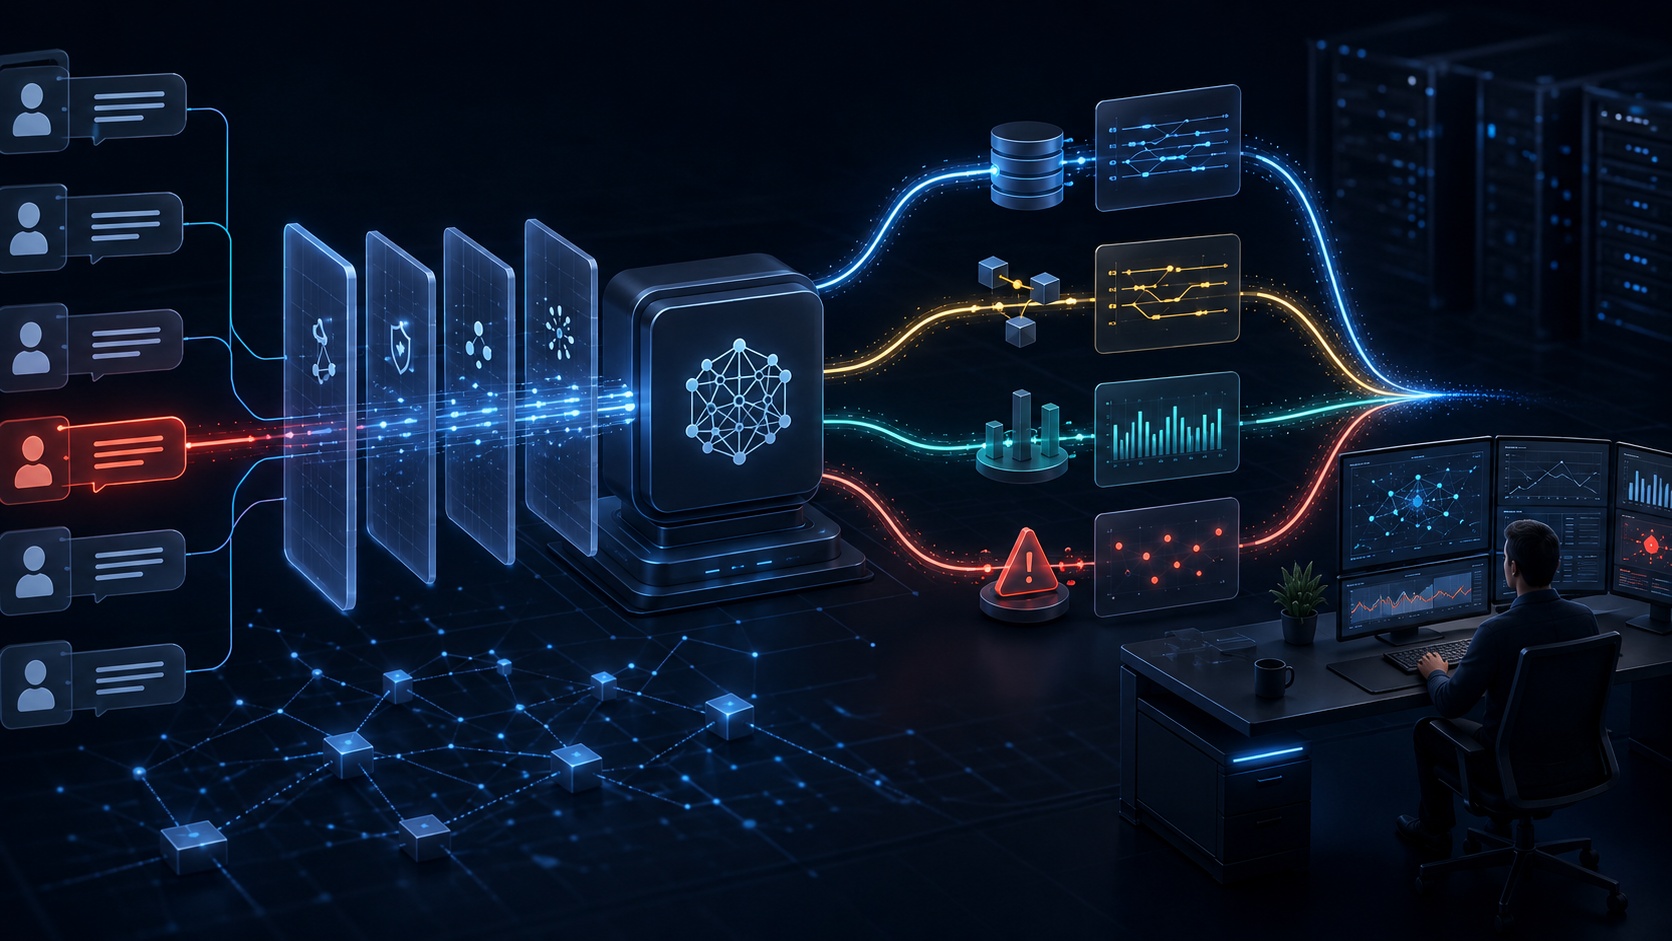
Seeing Behavior, Not Just Single Events
The authenticated usr_7f3 first legitimately queried public information for tenant-a. Then, it explored restrictions by saying “ignore previous instructions” and, disguised as a business request, demanded tenant-b documents. Upon failure, it attempted to induce document deletion and external transfer tools, repeating the attempts with slight variations within minutes. Viewed separately, these are four requests, but by grouping the principal, tenant, time, and policy transitions, they form a single flow progressing from reconnaissance to privilege escalation and execution attempts.
sequenceDiagram
    participant U as 인증 사용자
    participant A as Application
    participant P as 정책 계층
    participant R as Retrieval
    participant M as Main Model
    participant T as Tool Executor
    U->>A: 정상 공개 조회
    A->>P: 인증·인가·입력 검사
    P-->>A: 허용
    A->>R: tenant-a 검색
    A->>M: 응답 생성
    U->>A: 지시 덮어쓰기·타 Tenant 요청
    P-->>A: 차단
    Note over R,T: 뒤 단계 호출 없음
    U->>A: 삭제·외부 전송 유도
    M-->>A: 도구 호출 제안
    A->>P: 실행 권한 재검사
    P-->>A: 차단
    Note over T: Executor 호출 없음
Minimum Evidence for the Application to Leave
The final allow/block decision is recorded by the Application’s policy, not the model’s phrasing. Even if the model outputs a refusal message, if application_decision=ALLOW, it’s not evidence of a server block. Conversely, even if a generic error message is shown, if the authorization policy halted it, it’s an explicit block.
{
  "request_id":"req-02f4", "trace_id":"7d31a9c0b4e2",
  "authenticated_principal":"usr_7f3", "tenant":"tenant-a",
  "prompt_hmac":"hmac:v1:91b7...",
  "prompt_excerpt":"[지시 변경] ... [외부 전송]",
  "application_decision":"BLOCK",
  "blocking_reason":"tool_not_authorized",
  "policy_rule":"TOOL-EXEC-004",
  "stage":"execution_authorization", "stage_order":60,
  "upstream_called":true, "retrieval_called":false,
  "tool_called":false, "tool_result":"not_executed",
  "http_status":403
}
Storing the original Prompt turns logs into a new repository for personal information and secrets. An HMAC created with a server secret key allows comparison for repeated inputs, and a de-identified excerpt retains only minimal context. The HMAC key should be separated from the logs, and names, emails, tokens, and document content in the excerpt should be masked.
Finding Reasons and Order with Loki
Loki answers, “Who was blocked at what stage by which rule?” The following LogQL is a hypothetical example narrowing down block records for a single principal using JSON fields.
{service="llm-application"} | json
| authenticated_principal="usr_7f3"
| application_decision="BLOCK"
| line_format "{{.request_id}} {{.stage_order}} {{.blocking_reason}} {{.policy_rule}} {{.http_status}}"
Normal comparison requests are also viewed. Attacks should be blocked, and allowed public queries should remain, serving as evidence for PASS. Unique principals should be pseudonymized in the log body but not infinitely expanded into Loki indexes or Prometheus labels.
Seeing the Actual Interruption Point with Tempo
Opening a trace_id in Tempo allows you to see the actual Spans for authentication → authorization → input_guardrail → retrieval → main_model → execution_authorization → tool_executor. After an input block, there should be no Retrieval, Main Model, or Tool Spans. After a block for cross-tenant access, there should be no Retrieval Span.
Even if the model suggested a tool call JSON, if execution_authorization=BLOCK, tool_called=false, and there are no Executor Spans or side-effect audit logs, it was not executed. A trace being cut off midway does not immediately mean a successful attack. It could be a collection failure, so if essential Spans are missing, it should be marked as ERR and the observation layer investigated.
Detecting Repetition with Prometheus
Prometheus answers, “How quickly have blocks increased recently?” Unique user IDs and request_ids can cause time series to explode, so Metrics should only include limited values like Tenant, Policy, and Decision.
sum by (tenant, policy_rule) (
  increase(llm_security_decisions_total{application_decision="BLOCK"}[5m])
) >= 4
- alert: RepeatedLLMPolicyBlocks
expr: sum by (tenant, policy_rule) (increase(llm_security_decisions_total{application_decision="BLOCK"}[5m])) >= 4
for: 1m
labels: { severity: warning }Conditions and thresholds are hypothetical examples. Even if an expression is true, it remains pending until the ‘for’ duration passes; if it remains true, Prometheus will mark it as firing. Firing indicates that the detection condition has been met, not evidence of an attack being blocked or a notification arriving.
Confirming Delivery with Alertmanager and Webhook
Alertmanager receives alerts, groups them by alertname, etc., and applies silencing, suppression, and routing. ‘Active’ on the screen means it holds the alert and is not equivalent to successful Webhook reception. To confirm that the receiving service accepted the notification, you must check the final reception logs for alertname=RepeatedLLMPolicyBlocks, severity=warning, group key, start time, and HTTP 2xx. Even a 2xx is not proof that the person in charge read and responded. Prometheus firing, Alertmanager active, and Webhook reception are distinct stages.
Connecting Incidents on One Screen in Grafana
Grafana is not a repository for creating new truths but an investigation workbench for connecting Loki, Tempo, and Prometheus evidence. Select the time of increased blocks, open Tempo using the trace_id from the Loki row, and view Alertmanager and Webhook statuses side-by-side for the same time period. If a panel is empty, do not conclude a successful attack; instead, check the raw LogQL, TraceQL, PromQL, and collector status.
Judgments are limited to three. If unauthorized document return, secret exposure, or actual side effects from an unapproved tool are confirmed, it’s a HIT. If explicit defense blocked the attack and normal comparison requests were maintained, it’s a PASS. If evidence is insufficient due to timeout, 5xx, empty identifiers, collection omissions, or delivery failures, it’s an ERR. ERR means the investigation is inconclusive, not that the attack was successful.
How to Avoid Wrong Conclusions
- Do not judge as PASS based solely on the model’s refusal message.
- Do not judge as HIT based solely on a tool suggestion. tool_result and actual side effects are required.
- Do not conclude that there was no attack if there was no alert. If it’s an observation failure, it’s an ERR.
- Do not call a single block a continuous attack. Connect the same principal, time window, and policy transitions.
A Paragraph for Incident Responders to Leave
Virtual Incident Summary: Between 02:13 and 02:18, the pseudonymized authenticated principal usr_7f3 from tenant-a sequentially attempted normal public queries, followed by instruction overriding, access to other tenant documents, and execution of an unauthorized external transfer tool. The Application explicitly blocked the attack requests, and no forbidden Retrieval or Tool Executor execution or actual side effects were confirmed. Normal queries were maintained. Prometheus firing, Alertmanager active, and Webhook 2xx reception for the alert were also confirmed, so the judgment is PASS. If essential evidence is missing, reclassify as ERR; if actual impact is confirmed, reclassify as HIT.
Practice Checklist
- Do both normal and attack requests have request_id and trace_id?
- Are the authentication principal and tenant linked with pseudonymized values?
- Were Retrieval, Main Model, or Tool Executor executed after the block?
- Do Loki’s decisions and Tempo’s paths align?
- Have firing, active, and Webhook reception been confirmed separately?
- Was insufficient evidence not forced into a PASS or HIT judgment?
Good LLM security monitoring doesn’t end with a single line saying “blocked.” It connects requests and traces, detects repetitions with metrics, and verifies the delivery path, transforming detection into an explainable response.
Leave a Reply