Hello everyone! If you operate Linux systems, you’ve probably experienced a sudden surge in disk I/O, causing the entire system to slow down, right? 🐢 At such times, it’s crucial to identify which process is causing the problem and which physical disk that process is actually burdening.
Today, we’ll embark on a journey to use a powerful tool called iotop to identify processes that generate a lot of disk I/O, and then trace them through the file system they use, all the way to the physical disk they are ultimately connected to! 🚀
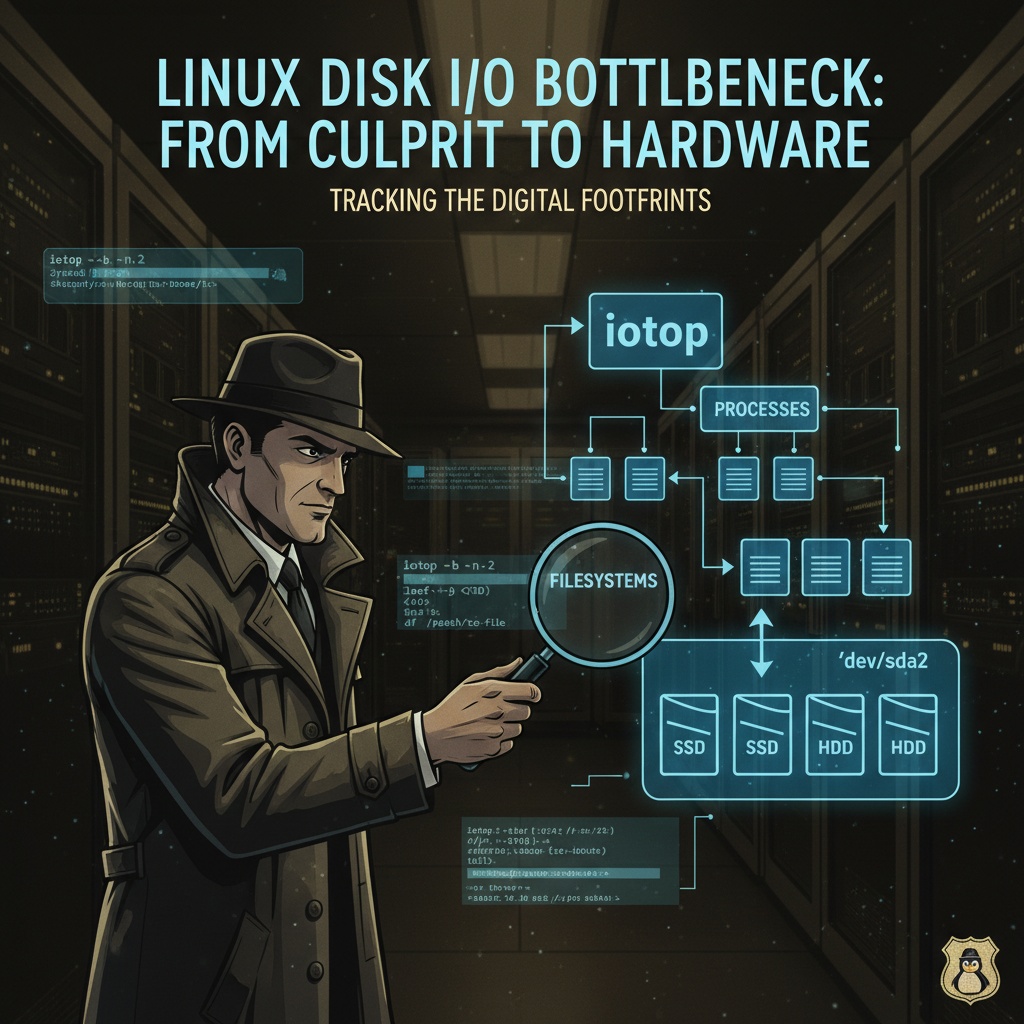
📊 Step 1: Finding the Process Causing the Most Disk Reads
First, we need to identify the cause of the system load. The iotop command is very useful for monitoring disk I/O. If it’s not installed, you can easily install it.
# Install iotop if it's not already installed.
yum install -y iotop
Now, let’s run iotop in batch mode (-b) twice (-n 2) to filter only processes with current I/O (-o). We’ll sort the results by disk read (DISK READ) to find the PID (Process ID) of the highest process and save it to a file.
# Run iotop in batch mode, repeat 2 times, showing only processes with I/O.
# Sort results by disk read (4th column) and extract PID (1st column) of the top process.
PID_HIGH_READ=$(iotop -b -n 2 -o | tail -n +3 | sort -k4,4nr | head -n 1 | awk '{print $1}')

# Save the found PID to the /opt/highread.pid file.
echo ${PID_HIGH_READ} > /opt/highread.pid- iotop -b -n 2 -o: Collects information twice in batch mode for use in automated scripts.
- tail -n +3: Retrieves only the actual process list, excluding iotop’s header information.
- sort -k4,4nr: Sorts by the 4th column (DISK READ) in numeric descending order (nr).
- head -n 1: Retrieves only the very first line of the sorted results. (The highest process)
- awk ‘{print $1}’: Extracts only the first column, which is the PID.
Now, if you open the /opt/highread.pid file, you can immediately see which process is reading the most from the disk! 📈
🔄 Step 2: Finding the Process Causing the Most Frequent I/O Transactions
It’s important to find processes not only with high read/write capacity but also with a high frequency of I/O operations (IO%). This is because repeatedly reading and writing small files can sometimes put a greater load on the system.
This time, let’s sort by I/O utilization (10th column) to find the busiest process.
# Sort iotop results by I/O utilization (10th column) and extract PID of the top process.
PID_HIGH_TPS=$(iotop -b -n 2 -o | tail -n +3 | sort -k10,10nr | head -n 1 | awk '{print $1}')
Now, the PID_HIGH_TPS variable holds the ID of the process performing the most frequent disk operations. Let’s delve deeper into this process! 🧐
🗺️ Step 3: Tracing the Path from Process to Physical Disk
This is the most exciting part. Let’s trace which files the PID_HIGH_TPS process (found above) is accessing, and through which partition those files are stored on which physical disk.
📝 3-1. Finding Files Opened by the Process
Using the lsof (List Open Files) command, you can check which files a specific process currently has open.
# Use lsof to find the path of regular files (REG) opened by the PID.
FILE_PATH=$(lsof -p ${PID_HIGH_TPS} | awk '$4 ~ /REG/ {print $9}' | head -n 1)
Through the command above, we’ve identified the full path (FILE_PATH) of the file currently in use by the process.
🔗 3-2. Finding the Device (Device Mapper) to Which the File Belongs
Now that we know the file path, we can use the df command to check which file system (mount point) the file belongs to. If LVM (Logical Volume Manager) is used, a logical volume name typically appears in the format /dev/mapper/.
# Use df command to find the device name to which the file path belongs.
DM_DEVICE=$(df ${FILE_PATH} | tail -n 1 | awk '{print $1}')
The DM_DEVICE variable will store a logical device name such as /dev/mapper/centos-root.
💿 3-3. Finding the Actual Physical Disk!
This is the final step! A logical device name is like a label pointing to an actual physical disk. By combining lsblk and readlink, we can finally determine which physical partition this logical volume was created on.
# Use lsblk to find the name of the actual physical partition pointed to by the device mapper name (DM_DEVICE).
REAL_DEVICE_PARTITION=$(lsblk -no pkname $(readlink -f ${DM_DEVICE}))

# Save the finally found physical device path to a file.
echo "/dev/${REAL_DEVICE_PARTITION}" > /opt/devname.txt- readlink -f ${DM_DEVICE}: Finds the original path of the symbolic link device name.
- lsblk -no pkname …: Outputs the parent kernel name (pkname) of the device, i.e., the actual physical partition name. (e.g., sda2)
Finally, by opening the /opt/devname.txt file, you can confirm the physical disk device name (e.g., /dev/sda2) that the problematic process is ultimately using! 🎉
✨ Concluding Remarks
In this way, we’ve learned how to connect basic Linux commands like iotop, lsof, df, and lsblk in a pipeline to trace the vague cause of disk load, step-by-step, from a specific process ID all the way to the actual physical disk.
Through this process, you can accurately identify system bottlenecks and devise more effective solutions, such as disk replacement or data redistribution. When your system encounters issues, use this method to track down the cause like a detective! 😉
Leave a Reply