Hello! When processing large-scale data, you’ve probably experienced system instability due to unexpected Out of Memory (OOM) issues. 😟 Today, we’ll take a closer look at memory_limiter, a crucial processor that prevents these troublesome problems.
In particular, there’s a golden rule that must be followed when using memory_limiter, and this rule determines the stability of your system.
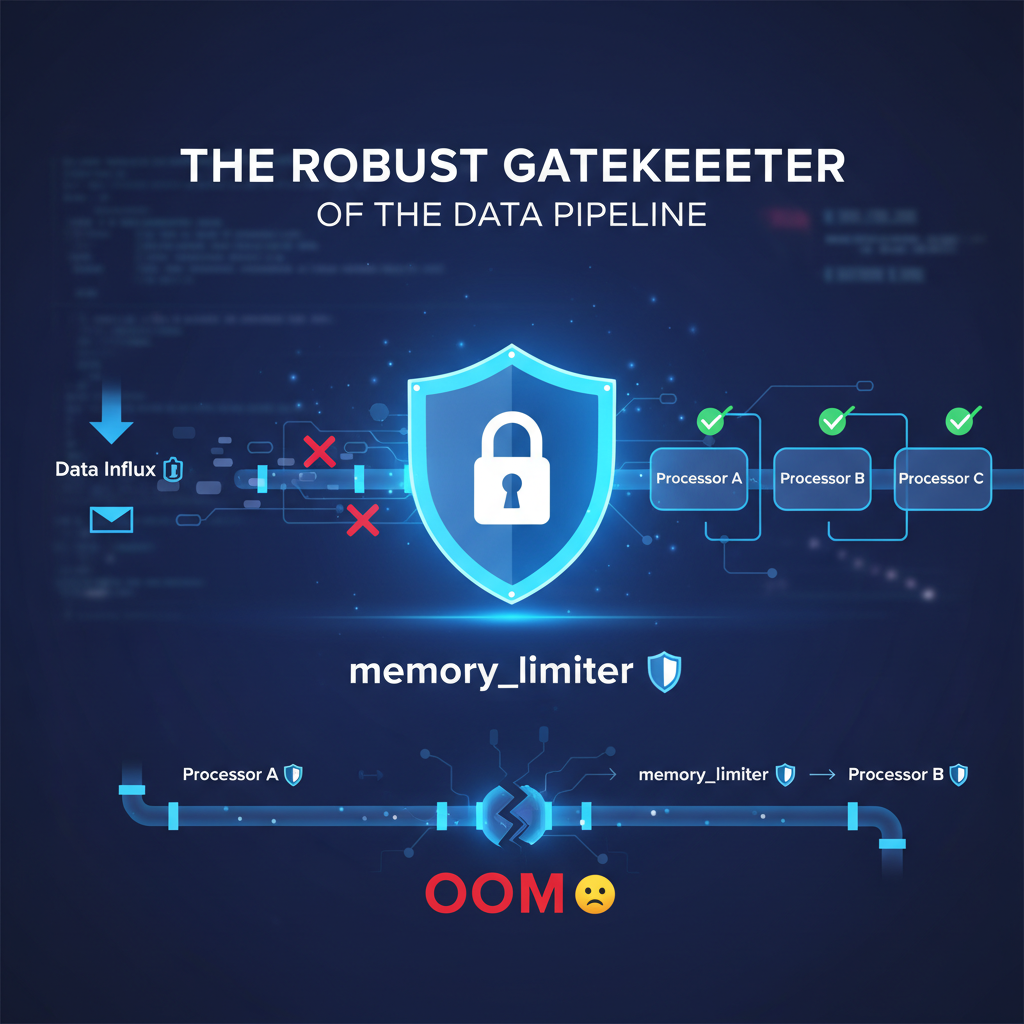
🤔 What is memory_limiter?
It’s easy to understand memory_limiter if you think of it as the ‘memory guard’ of a data processing pipeline.
Its role is very clear.
- Monitor Data Inflow 📥: It captures the moment new data enters the pipeline.
- Check Memory Usage 🧐: It monitors the system’s current memory usage in real-time.
- Compare with Threshold ⚖️: It compares whether the predefined memory limit (threshold) has been exceeded.
- If Safe (Below Limit) ✅: It safely passes the data to the next processor.
- If Risky (Over Limit) ❌: It boldly drops the data to protect the system.
Through this process, it prevents excessive memory usage, thereby averting terrible OOM situations that could halt the entire application.
✨ The Most Important Golden Rule: “Always at the Very Beginning!”
There is the most, most, most important rule in configuring memory_limiter.
memory_limiter must always be defined as the very first processor in every pipeline.
Why must it always be ‘first’? The reason becomes clear when you consider its role and operational order.
✅ The Correct Order (The Right Way)
This is the case where it acts as a gatekeeper at the very front of the pipeline.
Data Inflow ➡️ [🛡️ memory_limiter] ➡️ [⚙️ Other Processor A] ➡️ [⚙️ Other Processor B]
- As soon as data enters, the gatekeeper (memory_limiter) checks the memory status.
- If memory is sufficient, it allows the data to pass, and only then do other processors (A, B) receive the data and begin work, using memory.
- If memory is insufficient, the data is blocked from entering the pipeline in the first place.
Consequently, since it detects and blocks risks ‘before’ other processors process data and use memory, the memory protection function is 100% effective. 👍
❌ The Incorrect Order (The Wrong Way)
What if memory_limiter is placed after other processors?
Data Inflow ➡️ [⚙️ Other Processor A] ➡️ [🛡️ memory_limiter] ➡️ [⚙️ Other Processor B]
- When data enters the pipeline, Processor A receives the data first.
- Processor A already loads data into memory and uses resources to process it. 💥
- Only then does the gatekeeper (memory_limiter) belatedly check the memory status.
At this point, Processor A has already used memory, so even if memory_limiter detects an out-of-memory condition, it might be too late. It’s like locking the barn door after the horse has bolted. 🤦♂️
Conclusion
memory_limiter is a very powerful and essential tool for maintaining the stability of data pipelines. However, its power is only unleashed when it is in the ‘correct position’.
If you want to protect your valuable system from OOM, always ask yourself this question first when configuring your pipeline:
“Is my memory_limiter reliably guarding the pipeline at the very front?”
We support you in building stable data pipelines! 💪
Leave a Reply